Fleetgenius can help organizations streamline routing, compliance visibility, and day-to-day fleet decisions using a centralized operations view. This guide provides objective background on fleet-management workflows, what “fleet intelligence” typically covers, and how teams evaluate software providers. It also outlines practical selection conditions, requirements, and common implementation considerations for logistics and mixed vehicle operations.
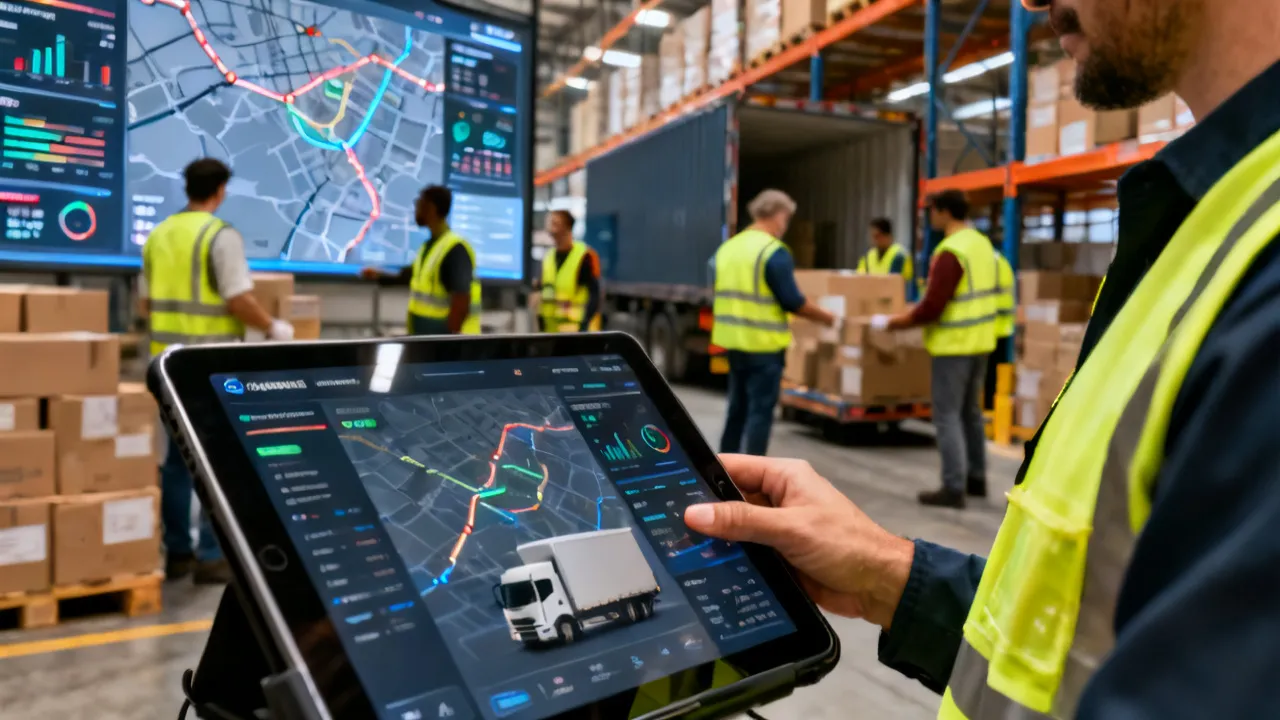
When fleets become larger—or more complex—manual planning and scattered spreadsheets quickly turn into operational risk. Fleetgenius is positioned as a fleet-management and operations-support solution designed to bring scheduling discipline, clearer decision-making, and better fleet oversight into a single workflow. In this article, you’ll find an objective, industry-informed view of how fleet intelligence systems are evaluated, what they typically include, and what teams should verify before committing to a supplier.
Because fleet operations are deeply connected to safety, reliability, and regulatory accountability, evaluation needs to be more than a feature check. Teams need clarity on how the system will behave on a difficult day—when data is missing, when schedules slip, when a vehicle is out of service, or when an incident triggers extra documentation and reporting. That is why a practical approach matters: it reduces procurement “surprises,” improves onboarding success, and ensures adoption by the people who actually run daily operations.
Modern fleet operations generally revolve around a few recurring pressures: maintaining service quality, keeping drivers and vehicles compliant with relevant rules, optimizing routes and dispatch efficiency, and generating trustworthy records for audits or internal governance. Whether your fleet is centered on delivery routes, field service, or regional transport, the core challenge is consistent: decisions must be made quickly, based on accurate information.
That is where solutions such as Fleetgenius tend to focus. Rather than treating fleet management as isolated functions (routing in one place, maintenance in another, compliance records in a third), fleet intelligence aims to unify operational inputs into a coordinated view—so managers can spot exceptions, plan more reliably, and reduce time lost to rework.
To make this concrete, consider the day-to-day “pressure points” that usually trigger spreadsheet dependence in the first place:
Fleet intelligence systems are appealing because they promise to reduce these gaps by providing a coordinated operational record. But the practical question becomes: does the system integrate with how your organization works, or does it impose a new structure that requires extra manual re-entry?
Although specific features vary by supplier and deployment model, fleet-management platforms commonly address the following categories. Consider these as evaluation lenses rather than assumptions.
From an expert operations standpoint, the “right” system is the one that supports your daily execution, not just your reporting. The value is highest when the platform reduces friction for dispatchers, makes compliance easier to maintain, and gives managers enough transparency to intervene early.
To evaluate these capability areas more practically, it helps to ask “what happens when something goes wrong?” For example:
The point is not that every system will solve everything automatically. The point is that the platform should provide a clear operational path for exception handling, decision logs, and audit-friendly history.
Because you did not provide explicit price figures or currency, this section stays objective and avoids unverifiable numbers. In fleet-management deployments, the total cost of ownership often depends on factors such as:
Beyond those factors, some teams also consider operational cost implications that aren’t billed directly by a vendor but still influence the economic outcome:
Practical takeaway: when comparing Fleetgenius (or any supplier in the same category), request a clear cost breakdown: subscription or license basis, integration fees (if any), onboarding timeline, and what support is included. Avoid negotiations that only compare headline pricing without accounting for implementation and integration.
Supplier due diligence should be grounded in operational needs and auditability. Here are items an industry-focused procurement and operations team typically validates.
From an expert perspective, “supplier confidence” comes from evidence: referenceable case studies, documented implementation paths, and transparent answers to integration and governance questions. In many unsuccessful projects, the vendor is not necessarily “bad”—the issue is that internal expectations are unclear, or the deployment plan assumes resources that the customer does not actually have.
To avoid that, teams should request:
Also consider the “human layer” of delivery. Operational systems succeed when the supplier’s deployment team understands your operational context, not just the technical requirements. During evaluation, you can test this by asking for realistic workflows and asking how the supplier has implemented similar workflows in comparable environments.
Your prompt does not specify an explicit city or country keyword that needs replacement. If your organization serves a region described as nearby, it’s still worth recognizing that fleet operations are shaped by local dispatch norms, road patterns, typical delivery windows, and regional compliance expectations. Teams in distribution-heavy markets often emphasize turnaround-time discipline, while field-service organizations may prioritize visit scheduling accuracy and documentation completeness.
When onboarding a platform such as Fleetgenius, ensure configuration supports your local operating rhythms—especially around working hours, holiday calendars, and how exceptions are reported to dispatchers and supervisors.
Localization can include more than calendar dates. A practical checklist of localization considerations might include:
The goal is to avoid a deployment that “works” in demo environments but fails when local rules and operational calendars differ from assumptions.
Fleet management rarely exists alone. In many organizations, fleet operations interact with:
Therefore, the evaluation question becomes less “Does it have feature X?” and more “Can it support our operational chain end-to-end without forcing manual re-entry of data?” A platform that creates duplicate record keeping often fails adoption goals, even if it looks strong in a sales demonstration.
To evaluate stack fit, teams can map “system of record” responsibilities. For example:
A practical evaluation ensures that the fleet platform does not become a second “source of truth” unless that duplication is intentional and well-governed.
The table below summarizes common requirements that organizations typically apply when comparing fleet-management suppliers such as Fleetgenius. No external links are included.
| Evaluation Area | What to Ask/Require | Why It Matters |
|---|---|---|
| Operational workflows | Map dispatch, planning, exception handling, and reporting to your current process | Ensures adoption and minimizes workarounds |
| Data integration | Specify how vehicles, driver info, and events are synced; confirm data formats and APIs availability | Prevents incomplete records and unreliable analytics |
| Compliance readiness | Confirm how documentation and audit trails are stored and accessed by roles | Supports governance and reduces audit friction |
| Security and access | Define user permissions, retention policies, and incident handling approach | Protects operational and personal data |
| Implementation timeline | Request a staged onboarding plan with milestones and responsibilities | Reduces disruption and clarifies accountability |
| Training and change management | Require training modules for dispatchers, managers, and drivers (as applicable) | Improves usage quality from day one |
| Support model | Clarify support hours, escalation paths, and what’s included | Ensures continuity after go-live |
| Total cost clarity | Obtain a full cost breakdown: subscription basis, onboarding effort, integration scope, and ongoing support | Prevents budget surprises and enables fair comparison |
In addition to these criteria, it’s often helpful to add evaluation questions that focus on reliability and data integrity. For instance, teams can ask:
Below is a practical, step-by-step approach that aligns with how many operations teams successfully deploy fleet software. Use it to structure your internal project plan when considering Fleetgenius or similar platforms.
Choose 3–5 operational outcomes you want to improve (e.g., fewer dispatch exceptions, better maintenance readiness tracking, faster resolution of service delays). Keep the metrics realistic and measurable.
Document how jobs are scheduled, how updates are recorded, and how exceptions are escalated. Identify where data currently becomes inconsistent.
Identify telematics sources, driver records, vehicle master data, maintenance history, and any enterprise systems. Confirm what will be migrated versus what will be referenced.
Specify the types of compliance artifacts you need to track and who must access them. Confirm role-based controls and audit trails.
Select a representative subset of routes or vehicles. Run the system in parallel until confidence is established, and then migrate workflows gradually.
Use real operational examples your dispatchers and managers face. For fleet systems, practice handling delays, missing data, and maintenance reminders.
Track completeness of key fields, the frequency of manual overrides, and how quickly issues are resolved. Adoption quality often predicts business impact.
After pilot success, expand to additional teams and vehicles. Use feedback to adjust rules, alerts, and reporting views.
To strengthen the guide further, consider adding “operational guardrails” that prevent pilots from failing for reasons unrelated to core product functionality. These guardrails often include:
These steps ensure the deployment is operationally resilient and not only technically successful.
Fleet intelligence projects are more likely to succeed when certain conditions are met. If any of these are missing, reconsider scope or strengthen internal readiness:
Another condition that often determines outcomes is the maturity of internal documentation and governance. Even the best fleet platform will struggle if operational procedures are undefined or inconsistent. During evaluation, teams can test governance readiness by asking:
If those answers aren’t available yet, the evaluation is still useful—but the implementation plan should include internal process definition and data governance work.
Organizations commonly use platforms like Fleetgenius to support structured planning, improved visibility into fleet status and events, and more consistent workflows for dispatch and compliance-related documentation. The exact scope should be confirmed in the supplier’s feature documentation and during a pilot.
In daily operations, teams often expect improvements in three areas: decision speed, documentation accuracy, and exception consistency. However, those improvements depend on configuration, integration, and user training. A fleet system might provide the “tools,” but it still requires operational mapping to ensure those tools are used effectively.
Request a cost breakdown tied to your deployment parameters: number of vehicles/users, integration scope, onboarding timeline, training deliverables, and support tier. Headline subscription pricing alone can be misleading if implementation effort differs significantly.
To compare fairly, teams should also request clarity on:
A fair comparison creates confidence that you’re evaluating total cost of ownership rather than a partial price view.
Integration expectations vary, but typical candidates include vehicle and driver master data, telematics feeds, scheduling/dispatch tools, and reporting or enterprise systems. Your evaluation should specify which systems are in scope and which responsibilities belong to your team versus the supplier.
When evaluating integrations, it’s also useful to request integration documentation that covers:
These details reduce the risk of discovering integration problems only after go-live.
Many fleet solutions can be configured for mixed operations, but configuration and workflow support must be validated. Ask for an example implementation approach that covers your operational model, including dispatch rules and event types relevant to each fleet category.
Mixed fleet types often create complexity because each category may have different compliance requirements, different job lifecycles, and different evidence artifacts. For example, delivery might prioritize route timeliness and proof of delivery evidence, while field service might prioritize visit notes, safety procedures, or work order completion documents. A strong evaluation tests whether the platform can handle these differences without forcing one model to fit all.
Clarify documentation structures, retention policies, and role-based access. Ask how the platform stores event histories and changes, and how users generate reports for internal reviews or formal audits.
Audit readiness is not only “document storage.” It includes:
During a pilot, teams can test audit readiness by attempting to generate a sample compliance report. The test should be performed with realistic record states (complete, partially complete, and exception conditions).
A safe pilot typically uses a representative subset of routes or vehicles, includes realistic peak-day scenarios, and tests both normal operations and exception handling. The objective is to measure data completeness, workflow adoption, and operational outcomes—not only dashboard appearance.
“Representative subset” often means choosing vehicles and routes that reflect actual complexity. For instance:
This prevents the pilot from overestimating success due to only ideal conditions.
Timelines depend on integration needs and training scope. During evaluation, request a staged plan with milestones. A responsible supplier will propose a clear onboarding path and define acceptance criteria for each phase.
Implementation duration can be influenced by factors such as data readiness, the need for custom workflow configuration, and the availability of internal resources for testing and training. Teams should therefore request a timeline that includes time for:
A timeline that skips testing often leads to post go-live instability.
Choose KPIs that reflect operational impact, such as on-time performance, reduction in manual dispatch interventions, improved maintenance readiness tracking, or faster resolution of exception tickets. Keep KPIs aligned with the objectives you defined at the start.
To select KPIs that matter, teams can structure metrics into categories:
KPIs should also include “leading indicators,” such as adoption rates and data completeness during the pilot—because if those don’t improve early, operational benefits often take longer (or never materialize).
Because you did not request specific statistics, this article avoids speculative performance claims. When teams do require external benchmarking, they should rely on credible sources such as government transportation agencies, recognized industry research organizations, and official regulatory materials. For example, if your fleet is subject to safety or compliance mandates, consult the relevant authority’s published guidance and reporting requirements rather than relying on vendor commentary alone.
For procurement teams, a key step is to separate “what is measurable” from “what is promised.” If a vendor claims improved compliance outcomes, teams should ask for evidence that connects the claim to measurable mechanisms. For example:
This approach does not assume the vendor is unreliable; it simply ensures decisions are evidence-based.
It’s also useful to align evaluation artifacts with standards your organization uses internally—such as internal security review frameworks, audit readiness policies, and data governance policies. If those standards exist, request vendor documentation that maps to them.
In fleet operations, the very valuable software tends to reduce uncertainty: it makes it easier to plan, spot exceptions, maintain compliance records, and coordinate day-to-day execution. Fleetgenius should be evaluated through workflow fit, integration readiness, governance support, and implementation discipline—not solely by feature lists or generalized promises. With a structured pilot, clear requirements, and measurable objectives, you can determine whether the platform supports your operational reality and delivers sustainable improvements.
To make the conclusion actionable, here is a final practical lens teams often use during procurement: if the platform were live tomorrow, could your dispatch team operate successfully without reverting to spreadsheets? Could your compliance owner produce an audit-ready report without manual stitching? Could your maintenance coordinator see vehicle readiness impacts in time to avoid disruptions? If the answers are “yes” after a well-designed pilot, the platform is more likely to become a durable operational foundation rather than a temporary reporting tool.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans
Explore the Tranquil Bliss of Idyllic Rural Retreats
How to Make Lasting Memories at Disneyland Attractions
4rkojvsx Technology: Industry Insights and Buying Guide
Affordable Phones and Plans for Seniors
Affordable Full Mouth Dental Implants Near You
Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!
Discovering Springdale Estates
Unveiling RS Sul Telecom Services
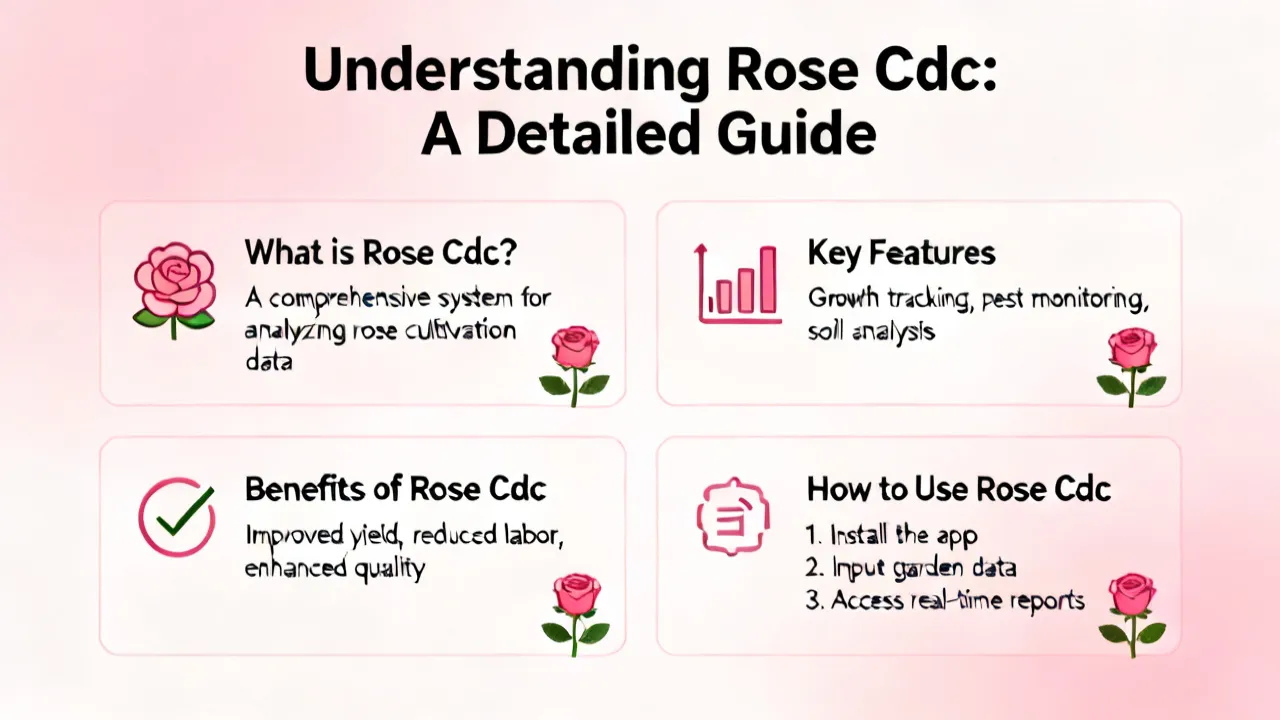
Understanding Rose Cdc: A Comprehensive Guide
This article provides an in-depth exploration of Rose Cdc, a term rapidly gaining attention in specific industries. Our discussion delves into the significance and application of Rose Cdc, its potential impact on various sectors, and expert insights into its future developments. This comprehensive analysis is designed to inform readers about the multifaceted aspects of Rose Cdc, its current applications, and potential advancements.
Understanding Compliance and AML Strategies
This article delves into the intricate realm of Compliance and Anti-Money Laundering (AML) strategies, highlighting their significance in the corporate world. Compliance AML refers to the organizational adherence to legal standards and regulations to deter financial crimes, ensuring transparent and ethical financial practices. This comprehensive guide examines these strategies' complexities and their pivotal role in safeguarding economic integrity.
Mastering Inbound B2B Strategies
The foundation of successful B2B strategies often lies in the effective implementation of inbound marketing techniques. In today's globally connected business environment, inbound B2B strategies have become critical for companies seeking to engage target audiences, optimize lead generation, and establish long-lasting partnerships. Understanding these strategies is essential for companies aiming to thrive in competitive markets.
Exploring B2B MBA Opportunities
Dive into the dynamic world of B2B MBA programs, designed for professionals seeking to enhance their strategic and management skills in a business-to-business context. This comprehensive guide discusses the significance of B2B MBAs in today's market, highlighting how these programs equip leaders with the expertise to navigate complex B2B relationships and drive business success.
Understanding Whitewater Regenerative Blowers
Whitewater Regenerative Blowers are essential in various industrial applications for their efficiency in moving air and gases. These blowers are known for their durability and ability to operate continuously, making them a preferred choice for industries ranging from wastewater treatment to aquaculture. This article explores their features, benefits, and applications, offering readers a comprehensive understanding of their importance in modern industry.
Mastering Employee Retention Strategies
Employee retention has become a critical aspect of organizational success, particularly in the dynamic landscape of 2020. As businesses strive to maintain a stable and productive workforce, understanding effective retention strategies is essential. This article delves into key methods for enhancing employee satisfaction and retention, offering a comprehensive guide for HR professionals and business leaders alike.